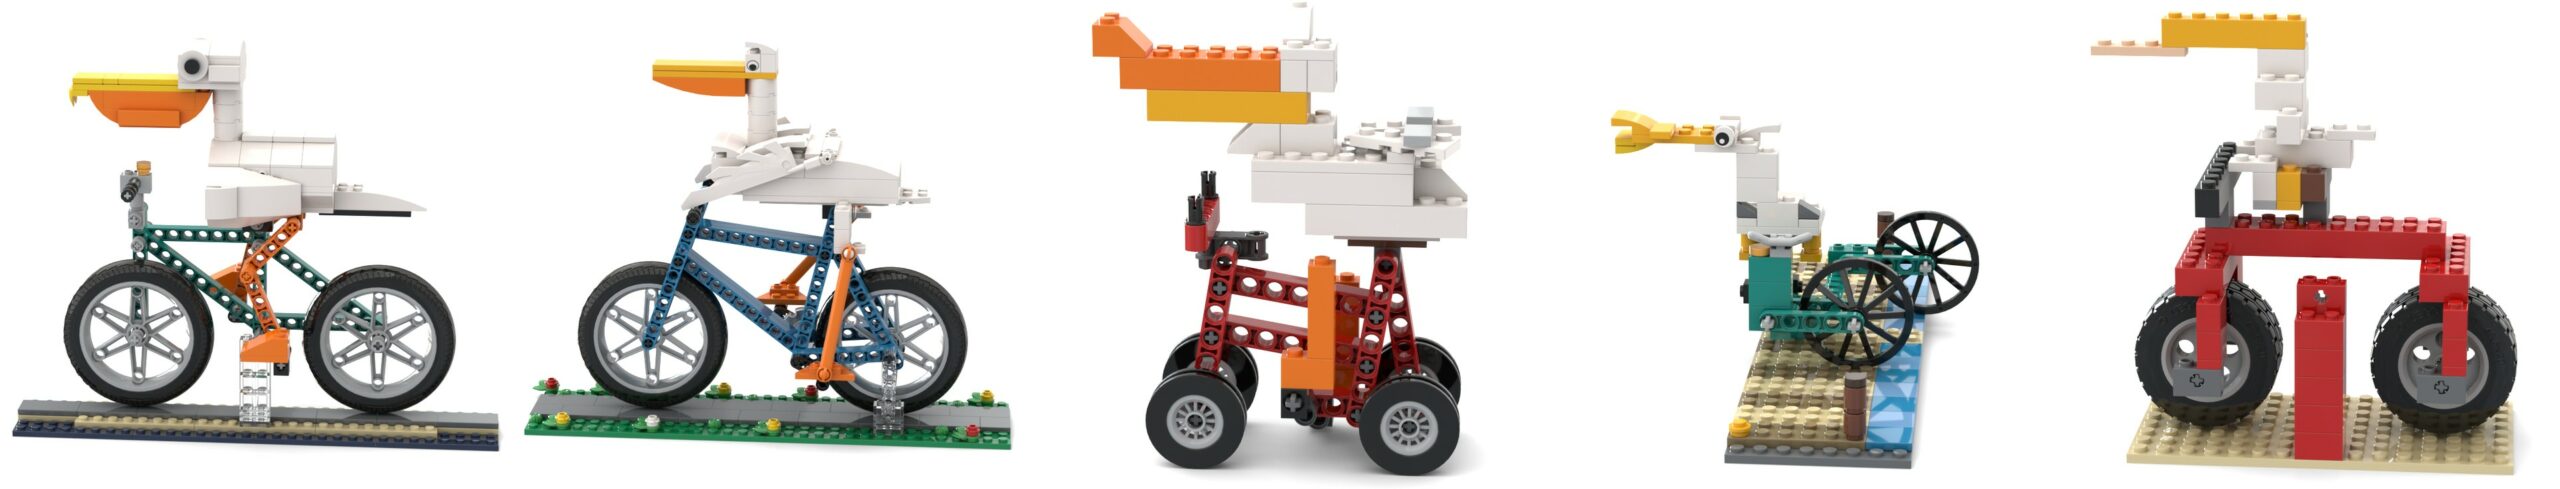
Give an AI a prompt, get a picture. That is the old game. BrickBench plays a harder one: build a LEGO model from text that snaps together from real parts and does not fall over. It is the first benchmark that scores an agent on whether its creation can be physically built.
The Story
BrickBench comes from Peter Kulits, Yiqing Xu, R. Kenny Jones, Cordelia Schmid and Jiajun Wu, a team across Stanford, the Max Planck Institute for Intelligent Systems and Inria. The paper landed on arXiv on 8 October 2026.
The idea is simple to say and hard to pass. You give an agent a sentence. It has to pick parts from a fixed LEGO library, place them, and hand back an assembly that is valid: it fits the part budget, has no collisions, and stays standing in a physics simulation. Then the build is scored on three things — is it buildable, does it match the prompt, and is it any good.
There are 300 prompts, 100 each across three settings. Model caps builds at 400 parts. Set goes big, 400 to 4000 parts. Alt-Build is the cruel one: you only get the 783 pieces from a single retail set, number 10698, and must make something new from exactly those bricks. Prompts span ten themes drawn from the BrickLink Designer Program.
The team also shipped the thing that makes it work: BrickAgent, an environment where an agent can search for parts, place them with a connector system, build subassemblies, render the result, and run a validator. The validator checks connections, collisions, and stability in a PyBullet physics simulation.
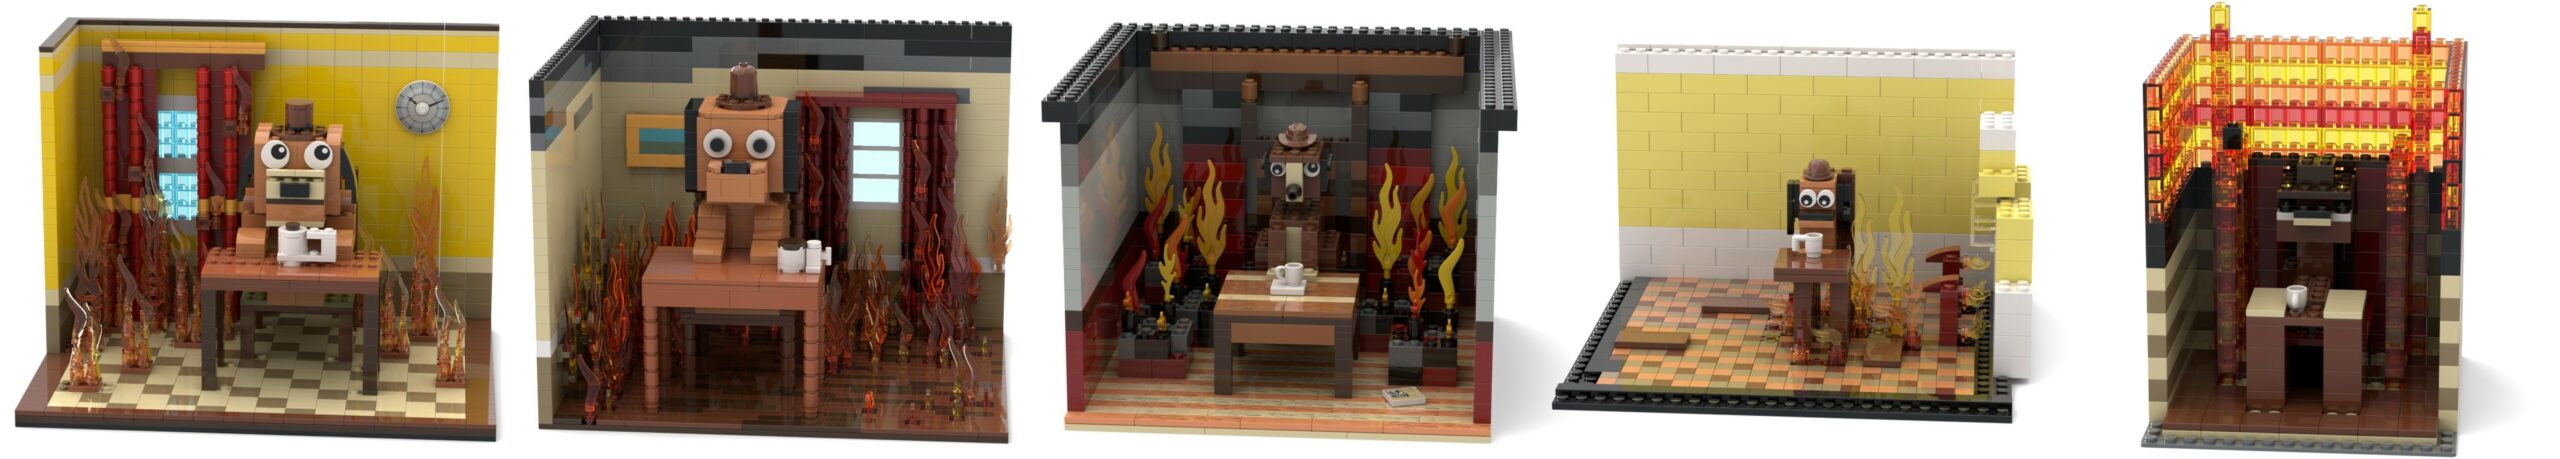
Eleven frontier agents were tested, among them GPT-6 Astra, Claude Opus 5.5, Gemini 3.8 Flash, Qwen 3.8 Flash, DeepSeek V4.1 Flash and GLM 5.3 Flash. The headline: five agents produced a valid build for every single prompt. On matching the prompt (the VQA score), GPT-6 Astra led at 0.954; GLM 5.3 Flash trailed at 0.590.
The environment is doing heavy lifting. In an ablation, the team took BrickAgent away. One model’s valid rate collapsed from 1.00 to under 0.01. Without the tool to inspect and validate, the agents were guessing.
Why You Should Care
This is the quiet shift the Lab keeps pointing at. The interesting result is not a prettier model. It is a general coding agent, with no LEGO-specific training, beating purpose-built brick networks because it can use tools, check its own work, and try again.
The old fine-tuned baselines show why that matters. BrickNet-14B was valid on only 26% of prompts. BrickGPT was valid 1.00 of the time but answered just 2.4% of the prompt’s requirements — it builds stable blobs that are not the thing you asked for. The agents, using BrickAgent, did both at once.
Swap “LEGO” for “game asset”, “modular set piece” or “parametric component” and you see where this goes. Buildable-by-construction, physics-checked generation is exactly the loop 3D and game pipelines need. The constraint is the feature.
There is still a wall. Five human raters picked the human-designed build over the agent one in 323 of 360 comparisons. No agent got mistaken for a human more than one time in five. The paper’s own line says it best: “Agents are learning to build what works, but not yet what makes a great design.”
Try It / Follow Them
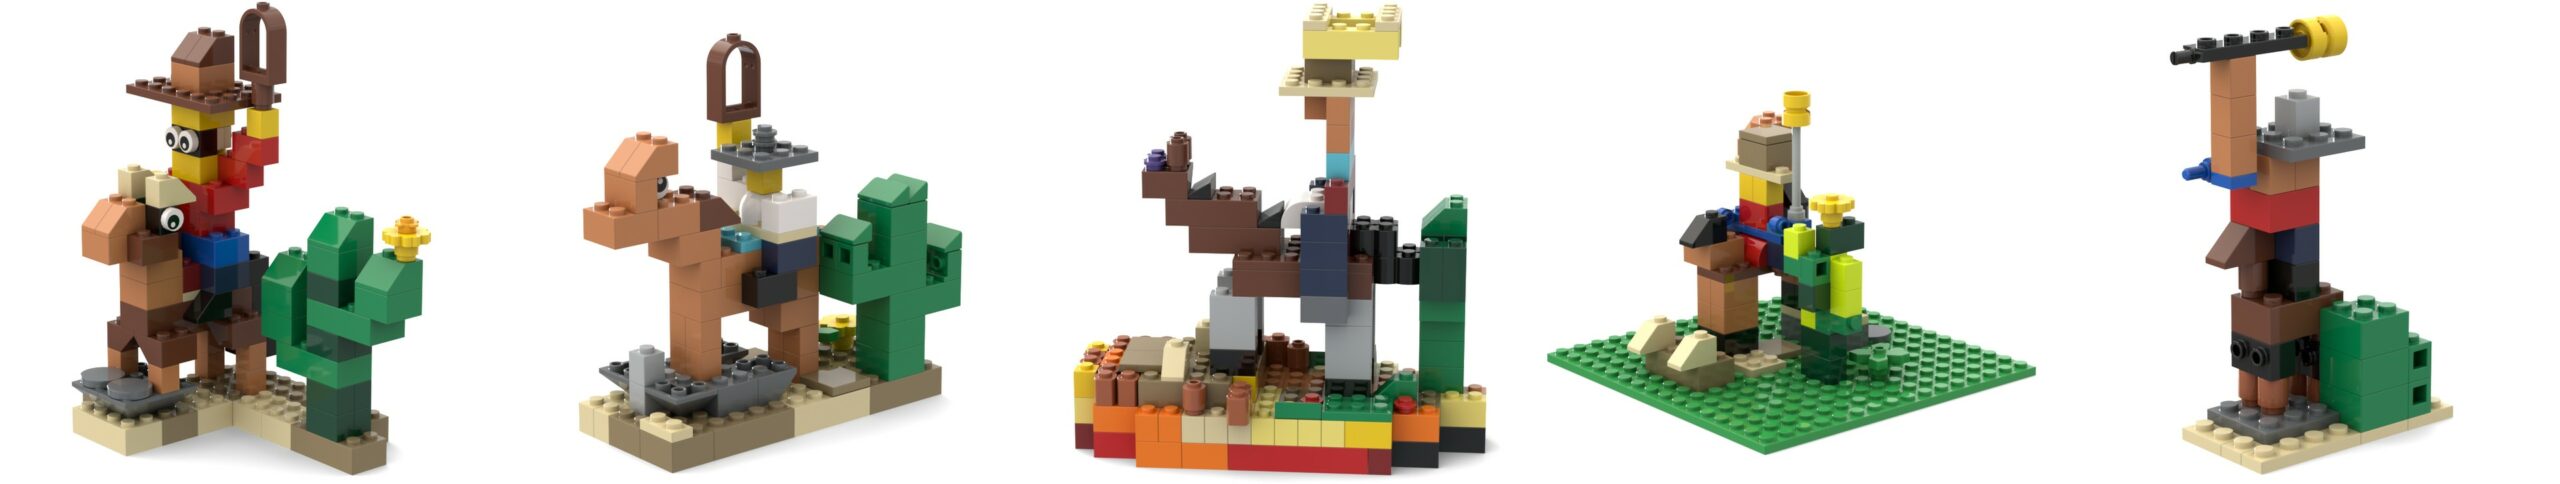
Everything is open. The project page is at brickben.ch, with a gallery where you can compare how each agent read the same prompt. The paper is on arXiv (2610.12452), and the project page links the code repository and a PyPI package for the environment.
The gallery alone is worth ten minutes. One prompt — a burning green dumpster, a mailroom conspiracy board, a dolphin under a rainbow — rendered a dozen different ways tells you more about how these models “think” than any score table.
IK3D Lab Take
We did not run the benchmark ourselves — this is a read of the paper and the project page, not a hands-on test. So treat the numbers as the authors’ own.
That said, BrickBench is our favourite kind of AI story: not a flashier generator, but a sharper question. It makes “can you actually build this” a scored, simulated gate, and that is the honest bar for any generation tool a maker would trust. The LEGO framing is playful, but the lesson is dead serious for game and 3D work — a general agent plus a good validation loop beats a specialist model that cannot check itself.
Where it breaks, by the authors’ own admission: the physics check is a rigid-body proxy. It does not test whether a connection is strong enough to hold, only that parts touch and the stack stands in sim. And cost is real — the best agent ran about $4.06 per build, against fractions of a cent for the trained baselines. Quality is not yet free. But the direction is clear, and it is the one worth watching.
How this article was made: researched and drafted with AI assistance, then fact-checked against the original sources and reviewed by Issa before publication.